- Friday, 7 Dec 2012:
Accessibility Advent: beware focus events
- Thursday, 6 Dec 2012:
Accessibility Advent: give input elements sensible name attributes
- Wednesday, 5 Dec 2012:
Accessibility Advent: support the escape key
- Tuesday, 4 Dec 2012:
Accessibility Advent: hitzones should fill their visible area
- Monday, 3 Dec 2012:
Accessibility Advent: strip leading spaces
- Sunday, 2 Dec 2012:
Introducing Accessibility Advent
- Wednesday, 12 Oct 2011:
On Resolution
- Saturday, 17 Sep 2011:
What Schonfeld should have written
- Monday, 11 Apr 2011:
Exceptional improvements
- Friday, 8 Apr 2011:
Client-side routing, the teenage years
- Published at
- Friday 7th December, 2012
(Throughout Advent I’m sharing some hints as to how web developers can make my life as a speech recognition user easier.)
You know that thing with web Twitter where you hit “reply” on a Tweet and the compose box slides out? Yeah, I hate that.
This is a Dragon-specific issue. The way that Dragon’s dictation system works is that it keeps a “cached” view of what you’re editing inside Dragon, to avoid hitting the accessibility layer of the operating system all the time (it also enables some editing features that wouldn’t otherwise be possible). As you dictate, it updates its cache and issues commands to the application to update the real copy at the same time. The trouble is, under a range of common situations these two views get out of sync, necessitating a special command to force Dragon to update the cache. Worse, it (and what I assume are some other bugs or problems between Dragon and the various applications you want to use) result in errors in the “real” copy in the application – spurious characters, usually.
Dragon’s response to this, as of this year’s release, is the Express Editor, which you can open anywhere, get Dragon’s full dictation and editing facilities without the inter-application problems, and then transfer the text from the Express Editor back into whatever you were using before – in this case a web browser with Twitter open.
That’s where things go wrong with Twitter replies, because when the browser window lost focus (so the Express Editor could grab it) Twitter helpfully collapsed the reply box to a single line – the same as if you’d clicked off it – and in so doing lost the focus on the input element. When the Express Editor subsequently tries to transfer its text back in, the focus is nowhere useful and you lose the text entirely.
Twitter have clearly designed this feature with care – once you start typing your reply, for instance, the input won’t collapse and lose focus. So this particular issue would be unlikely to occur to anyone who didn’t actually use Dragon.
What could Twitter do to fix this? I think that what’s happening is that they’re doing the collapse/unfocus on the blur event from the text area input. This is easier than binding a click handler to the document and making clicks outside the composition area perform the collapse/unfocus. The only differences I can think of are with switching away from the tab or application, which is what causes my problem, and if a browser plug-in takes focus within the same tab. I can’t think of a situation where a plug-in that grabs focus triggering composition area collapse would be a problem, but I also can’t think of a reason why not doing it would be a problem either.
The advice here? Blur events happen for reasons you may have forgotten about. Think carefully about how your site should behave when that happens.
- Published at
- Thursday 6th December, 2012
(Throughout Advent I’m sharing some hints as to how web developers can make my life as a speech recognition user easier.)
Autocomplete is my friend; things like email addresses are a pain to dictate. I could create a “word” in the Dragon vocabulary for each one I use, but it is vastly easier these days to let my web browser take care of it.
This does require that you play along, however. Use expected names for form inputs wherever possible. (They are scoped by the form itself, so collisions for the fields most likely to benefit from autocompletion won’t be a problem in most situations.) While we’re here, quit asking me to confirm my email address – because that second field usually doesn’t autocomplete.
What do you mean your inputs don’t have name attributes? Facepalm.
There’s a service called Launchrock that lets you take prelaunch interest by collecting emails. It’s simple. It’s cute. It doesn’t work.
Here’s what a keyboard user experiences: an email box plus some shiny information about whatever forthcoming service they are signing up for. Tap tap tap, email entered. Next field: choose a password. (It seems to support other fields, such as name, as well.)
Here’s what I get: the same email box and information. Great; email boxes I can just get the first character into, then up pops the autocomplete list and I select the one I want, which will usually be at the top.
“Press the key Juliet.”
Odd. The “j” is there, but no drop-down. Okay, maybe it triggers on two characters…
“Press the key Alpha.”
Still nothing. At this point I tend to give up. Seriously. Your site hasn’t launched, and when you do it will probably have Twitter or Facebook sign in, so there’s rarely much advantage in getting in early – and someone is bound to tell me about it again. If you’re really lucky, I’ll remember I’d heard of you before. And… I’m gone.
Launchrock’s developers are being clever, progressively revealing fields on a single page using JavaScript. Presumably at some point this gets submitted via Ajax. Apparently they forgot to build the non-JavaScript version first, or even at all; if they had, the inputs would have names, autocomplete would work and I’d be happy.
Please don’t do this. Build it right. (Apparently you can customize Launchrock’s HTML. Do so.)
- Published at
- Wednesday 5th December, 2012
(Throughout Advent I’m sharing some hints as to how web developers can make my life as a speech recognition user easier.)
I wrote yesterday about how moving the pointer by voice works; it’s a bit cumbersome, so forcing voice users to go that route isn’t great. Here’s another example.
Modal windows are an old desktop interface method requiring a specific interaction (such as confirming an operation) before continuing with normal application use. More generally, user interface modes are different states of the interface where it will respond differently to the same input (mouse clicks, keystrokes or whatever). Web apps are increasingly using modal techniques; done poorly they are a pain for voice users.
Two examples. The first: Twitter. If you click on a Twitter username, you get a modal sheet about that user. Clicking outside, or on the close button, dismisses it. So does pressing escape. Twitter also has a “new Tweet” button top right that is almost the same – except that escape does nothing. By voice, pressing a key takes about a second – compare to the problems discussed yesterday with controlling the pointer.
Second example: Google Reader. This has pretty good keyboard shortcuts, so I spend most of my time in it navigating by macros, saying things like “next news story”, “view original” and so on. The trouble with voice recognition is that it’s imperfect, so occasionally it will hear one thing and recognize it as something else, which ends up as dictation, i.e. basically just random keystrokes. (I could shift out into something called Command Mode, which won’t generate normal dictation; however I usually only think about that once something has gone wrong.)
Three keystrokes in particular do big things in Reader: “u” and “f” change the screen layout (and can be repeated to switch back), and “e” starts the “email this story” feature, from which there is no return (unless you tab to the cancel button, or move the pointer to click on it). The escape key apparently isn’t used while this feature is running, and would make things much easier. (Also, the email interface is inline, rather than floating over the rest of Reader as Twitter does things, making it less obvious that the feature is modal. That only confused me the first time, however.)
Simple rule: for interface modes, provide keyboard shortcuts.
Simpler rule: support the escape key.
Note this isn’t just for web apps; sites like Mother Jones have taken to using a floating layer to ask for donations. While it isn’t strictly modal (the site behind scrolls and links still work), since it obscures part of the content it’s effectively the same issue. Escape should close these kinds of things as well (or they should disappear automatically after a while – as advertising often does).
- Published at
- Tuesday 4th December, 2012
(Throughout Advent I’m sharing some hints as to how web developers can make my life as a speech recognition user easier.)

It’s probably fairly obvious how dictating text into, say, a mail client works, and even how voice commands to invoke menu items and keystrokes fit together. Let’s look at how voice control of the pointer works in Dragon. There are two different modes of operation, although they can be mingled, plus commands for clicking buttons, and pressing and releasing which enable dragging.
The first is the Mouse Grid: start by dividing the screen into a 3x3 grid, let the user select a grid square then centre the pointer in that square and subdivide into another 3x3 grid. Repeat until the user has moved the pointer to where they need it. You do this by saying things like “Mouse Grid / 1 / 3 / 7 / Close Mouse Grid”. (If you have multiple monitors, the first digit you say selects the monitor.)
The other is relative movement, by saying things like “Move Mouse Up And Left 3 Centimetres”. (You can also use inches, and “points”. None of them is a particularly obvious unit when staring at the screen; I tend to use centimetres.) If you aren’t sure about the distance you can go a bit more interactive, with “Move Mouse Up And Left”, watching it move, maybe saying “faster” and “slower” to control the speed, and finally “stop” when you’ve reached your destination.
My rule of thumb is to use relative for short or repeated movements (because going back and forth by a fixed amount is easy once you know what that distance is), and Mouse Grid for everything else.
Okay, fine. It’s a little cumbersome, but it works. What can we find to make it worse, so you can not do that and generally stop bugging me?
Remember Fitts’ Law: wider, closer things are faster to acquire. Closer doesn’t really apply here (except that longer distances are harder to guess, so relative movement is more likely to miss). Wider gives a margin for error, which applies with both relative and Mouse Grid movements, suggesting Fitts’ Law will apply here; although I haven’t actually checked for research confirming that, anecdotally it feels right based on my experience.
So how can you confound Fitts’ Law, beyond making your buttons tiny? By masking how tiny your buttons are. Here are two links. Which is bigger?
The left one is div > a with padding on the div. The right one is div > a with padding on the a. They look the same. They aren’t. Again, with an outline on the anchors:
(Apologies for the shoddy CSS; I didn’t have the patience to think it through any better.)
This affects everyone, but mouse users are close to where they need to be and can just slide around to find the hitzone. This kind of “looking with the mouse”, looking for the cursor to change or similar isn’t practical for voice users; speculatively moving a bit and trying again ("Move Mouse Right / Stop / Mouse Click") is much more expensive. Trying again with Mouse Grid is even worse.
Simple rule: hitzones should fill their visible area.
The formula at the top is for the Accot-Zhai steering law, a path-following generalisation of Fitts’ Law which should model using the Mouse Grid well.
- Published at
- Monday 3rd December, 2012
(Throughout Advent I’m sharing some hints as to how web developers can make my life as a speech recognition user easier.)
There are any number of strange effects of using speech recognition to drive a computer, but the one that affects almost everything I do – and that I forget most often that I have to take account off – is leading spaces. Dragon doesn’t always notice when you’ve moved between input elements, and when it doesn’t it assumes any dictation continues the previous sentence. This results in a leading space in the new input.
You can imagine all sorts of situations where this is a pain, but the one that annoys me most is when I have to put in credit card or banking details. (It can also be a problem with CAPTCHA, although usually less than figuring out what the messed up letters are in the first place.)
I’ll note in passing here that, yes, this is a software problem at my end: it should be possible for Dragon to get this right. Indeed if I remember correctly, Dragon Naturally Speaking on Windows doesn’t have this problem, and for that matter if I used Safari on Mac there are commands that can help navigate text inputs while telling Dragon what’s going on. I dislike Safari sufficiently that the alternative would be to go back to Windows, where Dragon Naturally Speaking provides better integration with Internet Explorer.
The leading space issue doesn’t just crop up with web forms – Glee Box itself suffers from it, for one, and sometimes the 1Password unlock screen gets a rogue space as well. I can say “no space” before a word to prevent the leading space, but I don’t always remember. I’d love it if web forms just stripped leading spaces so this never bit me, but it’s particularly annoying when it interacts with naïve validation.
Leading spaces should not be considered invalid in numeric fields. Most string to number conversion functions will happily skip them, and so should your validator, be it a regular expression or something more esoteric. This is equally true whether your validation runs on the backend or front-end (and, sidebar, it should run on both); if the latter then there’s another problem, which banking sites are particularly prone to run foul of.
Long numbers are hard to type in accurately (they’re easier to dictate, as it happens). One way of making things easier is to split them into shorter sequences – for instance, your credit card probably has four groups of four digits on the front instead of just one sixteen digit string. This is fine.
Similarly, to allow people to verify that they typed a number in correctly, some sites use multiple input boxes, building the single number in code somewhere. I haven’t seen this often with credit cards, but it gets used for software registration numbers a lot, and some banks split up the authentication codes coming in from PIN-based token generators, such as Barclays’ PINsentry.
As a web developer you see a requirement for two boxes each taking four digits, so you set the maximum length (maxlength) of each input to four.
[1234] [5678]
Then I come along with my leading space problem and this happens:
[ 123] [5678]
Actually it’s usually worse than that, because you’re clever so you advance the focus once there are four characters in the first input:
[ 123] [4567]
Then some other clever developer adds client-side validation to the form. One of two things happens, depending on where the focus is left. Most commonly, the focus seems to end up on a help link explaining what went wrong:
[ 123] [] ERROR!
If I’m lucky I can then tab back to the first input and try again. It’s around this point that I want to punch someone. (For reasons I don’t understand, inputting numbers in this stop-start staccato fashion is considerably more stressful than dictating prose and then correcting it.)
So what should happen? With client side validation, killed the leading space when it appears. Without (and this is going to upset some people), set the input maximum length to one more than you’re looking for (five, in this case) – and then deal with this properly in the backend so an input like the following still works:
[12345] [678]
Using client-side validation here is a Very Good Thing, clearly.
But wait, it gets worse. Say you read the above and decided one big input is better (as most people do for credit card numbers, for instance). You allow Allow the slightly larger input maximum length, strip any leading space, and then reuse that code when building an e-banking setup system, where an authentication code gets mailed through the post to confirm the user is who they say they are. You parameterize your widget based on code length. Two years later someone rolls it out for codes the same length as US phone numbers. Dragon helpfully formats my code as a phone number:
123-555-6789
So you should probably strip internal hyphens, and make the input maximum length even longer – in fact, I’m beginning to wonder if exact input maximum lengths are ever useful.
- Published at
- Sunday 2nd December, 2012
Recently I’ve noticed a particular kind of rage growing within me, a rage that has me tweeting bile and involuntarily punching imaginary developers sitting next to me. It is the rage caused by people who don’t think about accessibility when building (mostly) websites.
There are a million sites and articles that make the case that you should care about accessibility – features and techniques that help users of “assistive technology” – usually from a legal (local legislation requires you make efforts towards accessibility) or economic (you can make more money, yay!) standpoint. My argument is different.
I use assistive technology. When I encounter a poorly built website or piece of software, I wanted to punch the people involved. Eventually I won’t be able to constrain myself.
No one really wants that, so this Advent I’ll be giving some hints on how you, as a web developer, can make my life easier. I use Dragon Dictate for Mac, which uses the same voice recognition engine as Dragon Naturally Speaking for Windows; my advice will sometimes be specific to Dragon, and more commonly only considered from the point of view of speech recognition users – I’ll be trying to explain why these things are important to me, as well as what you should do. Nonetheless, the vast majority of things that people commonly get wrong are either general accessibility mistakes, or subtle details that are unlikely to cause problems for any other users if implemented the way I think they should be. If you disagree, or I’ve just got something utterly wrong, then let’s talk so I can improve my advice.
I’ll be publishing these weekdays during Advent. They aren’t in any particular order. I may forget to update the following list every day:
- Published at
- Wednesday 12th October, 2011
As soon as you scale beyond one host — in a data centre or in the cloud — you start needing a way to resolve services. Where previously every service — your database, your key-value store — was local to your application, now some will be on another host, and your software needs to find it.
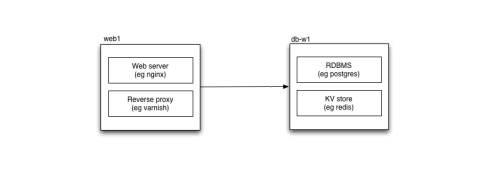
Services separated across two hosts
Probably the most common form of resolution currently is the Domain Name System, or DNS. (DNS is used as part of Active Directory, which you’ll probably use if you run a Windows-based data centre.) Using DNS has a number of advantages:
- wide support; every operating system you’re likely to use will have DNS support out of the box
- distributed, fault-tolerant, and secure
- you’re already using it (for mail routing, web routing and so forth)
Inside the data centre, you probably wind down the TTL (time to live) on DNS records, and either use dynamic DNS updates to change them or some sort of central control panel — so when you want to switch your primary database server, you flip a switch, and the hosts look up the new record inside a few seconds, and on we go. The main downside, beyond setting up all the pieces (which isn’t hard, but so many people are allergic to simple sysadmin tasks these days) is that you need somewhere to flip the switch from. Building that in a distributed fashion is hard, and most people don’t bother. (However you don’t flip the switch very often, and you can easily set things up so that even if the switch machine breaks, the rest of the system keeps on working.)

Switch between data servers using DNS in the data centre
Enter the cloud
From a certain standpoint, using cloud hosting such as Amazon EC2 makes no difference to this picture. In the cloud it’s more common to tear down and replace instances (hosts), but the shift between different available instances can be managed using configuration systems such as puppet or chef to update DNS easily enough. There is, however, a better way.
Let’s take a step back for a moment and ask: what are we trying to do?
What we want is a way to resolve from function to host. DNS allows us to do this by naming functions within a zone, but in the cloud there’s actually an existing mechanism that closely models what we want already: security groups. (Security groups seem to be only available with Amazon EC2 at the moment; it’s possible that you can do similar things using metadata keys with Rackspace, although you’ll have to do more work to tie it into your explicit iptables configuration.)
Security groups are a way of controlling firewall rules between classes of instances in the cloud. So it’s not uncommon to have a security group for web access (port 80 open to the world), or database access (your database port open only to those other security groups, such as your web servers, that need it). Although they’re called security groups, the most logical way of using them is often as functional groups of instances.
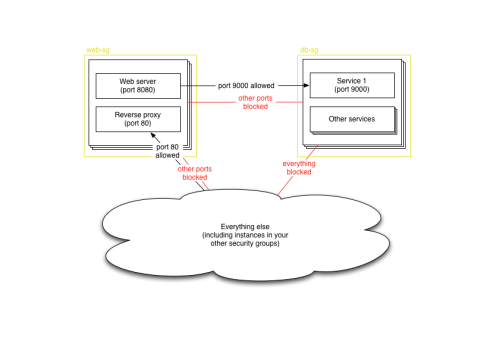
Two security groups in the cloud
Since you already need to define instances in terms of their security groups, why not resolve using them as well? The Amazon APIs make it easy for instances to find out which security groups they are in, as well as for other instances to look up which instances are in a particular group. Hosts can even be in multiple groups, allowing them to perform multiple functions at once.
This is how elasticsearch performs cluster resolution for EC2: you give it Amazon IAM credentials that can look up instances by security group, and a list of security groups, and elasticsearch will look for other instances in those security groups, bringing them into the cluster. Spin up a new elasticsearch instance in the right security group, and it joins the cluster automatically.
cloud:
    aws:
        access_key: AKIAJX4SKZVMGKUYZELA
        secret_key: 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

index:
    translog:
        flush_threshold:            10000

discovery:
    type: ec2
    ec2:
        groups:
            - airavata

gateway:
    recover_after_nodes:    1
    recover_after_time: 2m
    expected_nodes: 2

bootstrap:
    mlockall: 1
We do the same thing at Artfinder for our web servers to resolve database instances and so on.
AWS_REGION, AWS_PLACEMENT = get_aws_region_and_placement()
TPHON_HOSTS = find_active_instances("tphon", AWS_REGION)
DUMBO_HOSTS = find_active_instances("dumbo", AWS_REGION)
In some cases, you need to choose only one machine to use out of several in the security group, perhaps because you have several different instances with the same data available, or perhaps because you’re bringing up a new instance which isn’t yet ready. You could test connect to each one to find a genuine running service, or you could use EC2′s facility for tagging instances. We use a tag of af-status=ready on anything that’s in service, and we can check that when finding database instances, or when figuring out which machines should be attached as web servers to our load balancers.
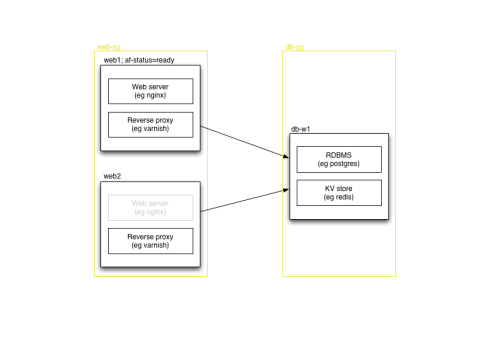
A new web server instance that isn't yet ready for use
We do this with a very simple filter on top of the security group-based instance resolution code:
from awslib.ec2 import instances_from_security_group

def find_active_instances(security_group, AWS_REGION='us-east-1'):
    def active(instance):
        if instance.state!='running':
            return False
        elif instance.tags.get('af-status', None) != 'ready':
            return False
        else:
            return True

    return filter(
        active,
        instances_from_security_group(
            security_group,
            region=AWS_REGION,
            aws_access_key="AKIAJX4SKZVMGKUYZELA",
            aws_secret_key="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",
            )
        )
Tags have a considerable advantage over security groups in that they can be altered after you spin up an instance; you could in fact use only tags to resolve instances if you chose, although since you still need to provide firewall rules at the security group level, a mix seems best to us.
Tags allow us to have a security group for all our backend data storage services — to start with everything’s always on one host — and then migrate services away smoothly, simply by moving tags around. (Obviously there is some complexity to do with replication as we migrate services, or some downtime is required in some cases.) We don’t have to deploy code, and we don’t have to wait for DNS changes to propagate (even with a low TTL there’s a short period of time to wait) — we just flip a switch, either in Amazon’s web console or via the EC2 API, both of which are already distributed and can be accessed from anywhere given the right credentials. Most crucially, the web console is already written for us — we have a small amount of code to take advantage of security group and tagging for resolution, and that’s it.
In actual fact, our running instances don’t re-resolve continually, since that’s a performance hit; but we can reload the code on command from fabric, from anywhere, as well, and they’ll resolve the new setup as they reload. Flipping a service from one machine to another takes a few seconds, on top of whatever work has to be done to migrate data.
Configuration management
In general if you make the same configuration change twice you’re doing it wrong. Configuration management allows you to specify how all your hosts are set up — packages installed, services running, everything — so you can apply it automatically to new hosts, or upgrade existing ones as configuration changes. Two of the most common configuration management systems today are puppet and chef — we use puppet. The crucial part when running several different types of host is to figure out which configuration to apply for a given host. One way is to use hostnames, or MAC addresses, but this doesn’t work well in the cloud where you can’t predict anything about an instance before you build it. However you can control what security group it’s in; we have a custom fact that looks up the security groups an instance is in and matches that to a configuration.
require 'open-uri'

groups = open("http://169.254.169.254/2008-02-01/meta-data/security-groups").read
groups = groups.split("\n")
groups = groups.select {|g| g != 'ssh-access' }
if groups.size > 0
  sec_group = groups.first
  Facter.add("ec2_security_group") {
    setcode { sec_group }
  }
  puts "SECURITY GROUP #{sec_group}"
end
We combine this with the Ubuntu EC2 AMIs’ user-data init script system to automatically puppetize new instances on startup. For instance, to bring up a new search server we just do:
fab new_airavata:puppet_version=2011-10-12T10.42.01
A few minutes later, our search cluster has a new member, and can start redistributing data within it. (Although it uses fabric, it’s actually just python using boto, an EC2 library. We use fabric to perform management tasks on existing instances, so it makes sense to use it to fire up new ones as well.)
It’s a bit more work to bring up a new webserver (currently we like to test them rather than putting them automatically in rotation at the load balancer), and database servers tend to be the hardest of all because they require hostnames to be set in textual configuration for things like replication configuration — although this can be managed with puppet, and we’ll get there eventually.
A slightly crazy idea
The big advantage of DNS over security group resolution is the ubiquity of support for DNS lookups. Since this goes right down into using DNS hostnames for resolution within configuration files (such as for replication setup, as mentioned above), it might be helpful to run a DNS server that exposes security groups and tags as a series of nested DNS zones:
; Origin is: ec2.example.com

1.redis.tphon                   IN A        10.0.0.1
2.redis.tphon                   IN A        10.0.0.2
3.redis.tphon                   IN A        10.0.0.3
1.postgres.tphon                IN A        10.0.0.3
2.postgres.tphon                IN A        10.0.0.4
1.readonly.postgres.tphon       IN A        10.0.0.5
2.readonly.postgres.tphon       IN A        10.0.0.6
We actually already do something similar for generating munin configuration, and it could be done entirely by a script regenerating a zonefile periodically; if anyone writes this, it’d be interesting to play with.
In summary
Although DNS is the most obvious approach to resolution on the internet, there are other options, and in Amazon’s cloud infrastructure it makes sense to consider using security groups and tags, since you are likely to need to set them up anyway. It takes very little code, and is already being adopted by some clustering software.
- Published at
- Saturday 17th September, 2011
Hopefully signalling the end of the dithering over whether TechCrunch will remain an entertaining, bitchy and sometimes accurate tech biz gossip site (Heat for the lives of web companies) or begin its gradual slide into tedium and obscurity (The New York Times for…well, for pretty much anything), newly-minted Editor-in-Chief Erick Schonfeld last night publicly accepted Paul Carr’s equally public resignation. It won’t actually be the end of the story, but a standard has been set, on both sides, and with Arrington off worrying about all the things VCs worry about and Carr indulging himself as only the unemployed can, the story at least should have reached a point where the majority of us can just ignore it without undue effort.
But Schonfeld missed a trick in writing such a dry acceptance. Now is the time, after all, to establish the new voice of TechCrunch, which is inevitably going to be different; he could also be taking concrete steps to demonstrate his independence from Arianna OnLine. So here’s what he should have written.
Disclosure: I'm an investor in Paul Carr, in that I've sunk money in two of his past projects. Although I probably made it back by working on Diageo campaigns.
For the last couple of weeks people have painted me variously as evil or inept, a mastermind or a puppet. I’ve never really thought of myself as either, but clearly I have to make a choice. Okay, then: I’ll be evil.
Paul Carr, one of our columnists who was hired for his grandstanding ways and has recently joined the hoardes outside the gate who just don’t understand my evil vision, has decided to fall on his own sword and quit very publicly on TechCrunch. I’m sorry, Paul, but that’s not acceptable.
Paul’s resignation post reads like the brave stand of a man of principle, but the truth is that Paul doesn’t really know what he is talking about. Only the evil genius has principles, long developed as he apprenticed under others. Henchmen can only have loyalty. Of course Carr thinks he is somehow being loyal to Mike, but that’s pointless. You can only have loyalty to someone who is there: henchmen can’t retain loyalty to someone playing the golden harp. They don’t have the imagination.
Naturally there will be changes as I take over the reins and put all the minions back in their traces (for instance, I’m tightening the use of language throughout everything we do, starting with the title: we’re now just CRUNCH, all in capitals like any proper evil organisation). I tried to reach out to Paul and was hoping to have an honest conversation about his future at CRUNCH (probably in Department III). Instead, he blindsided me with his post by publishing it as I was laughing insanely while playing with my pet shark.
In any other organisation, Paul would have been dealt with long ago. And his post would be taken down. But I will let it stand. When Paul was hired, he was promised that he could write anything and it would not be censored, even if it was disparaging to TechCrunch. I will still honor that agreement. But obviously there are forms I have to go through: I’ve changed the locks at CRUNCHQ, I’ve told all the other henchmen (and women) that Paul is a potential trouble source, and that they should disconnect from him. Also, I don’t want to brag, but I called in a couple of favours and…well, let’s just say that Paul probably shouldn’t go anywhere near Reno for a few years.
I am also not going to get into all the details of what happened behind the scenes during the drama which unfolded in the past few weeks here. But I will say this: to suggest that Arianna appointed me editor single-handedly is untrue. It took me weeks of preparation, thousands of dollars in bribes, and the tactical seduction of a judge on the Second Circuit. There must have been at least six hands involved. Possibly seven if we include a clerk hitting the light switch at the wrong time.
So I think we’ll all just have to agree to disagree on that one. Paul, you may think your hard work under Mike entitled you to certain benefits such as the right to leave at a time of your chosing. But when one chief succeeds another…well, we all know what happens to those who speak up for the old regime. So in fact I don’t have to accept your resignation; that was just you publishing your exit interview. In fact, if you think back carefully to that time when you “decided” you wouldn’t stay if Mike’s wishes weren’t honoured…your Diet Coke tasted a bit funny that night, didn’t it Paul? And when you went to bed, was your head spinning with rage, or with something else? I was there, Paul. I was there.
- Published at
- Monday 11th April, 2011
A while back I released a Django extension that makes it possible to raise exceptions for any HTTP status code. At the time this was mostly interesting to enable raising 403 Forbidden consistently; since the release of Django 1.3, and the introduction of class based generic views, this becomes more useful.
I’ve just uploaded a new version to PyPI which provides basic support for raising redirects as exceptions (basically, it does the exceptional processing even with DEBUG=True). At Artfinder I’m using it to implement slug redirects, where I’m overriding SingleObjectMixin.get_object to cope with slug changes without breaking old links; there are undoubtedly other useful things that can be done in a similar way.
At some point in the future, hopefully in Django 1.4, you’ll be able to achieve the same effect with some built-in support, but for the time being django_exceptional_middleware is still useful.
- Published at
- Friday 8th April, 2011
When I wrote about hashbangs, deep linking and ghettoised browsers, I genuinely thought I’d be able to punch out the second article within a couple of weeks. I failed utterly, due to a combination of illness, my company decloaking its new website, and a fair dose of general uselessness. But here we are again.
One of the main things I tried to do last time was to point out the problems that hashbangs bring; but with some common sense, namely that sometimes you have to go down this route. Since hashbangs are a way of mitigating the problems associated with client-side routing (CSR), the issue becomes: what are the benefits of CSR?
CSR does one thing, and one thing only: it allows you to change content on a web page without forcing a complete page load. This can be used in a couple of significant ways:
- Protect client-side state (eg: long-running client side processes such as media players) from being disrupted during the page load
- To ensure that the client interface remains responsive through loading new content
In fact, the second is in some ways just a particular use of the first, although in practice they’re significantly different and so should be treated separately.
Enemy of the State
A page load wipes out a whole bunch of stuff: all your Javascript variables are gone, the whole DOM is thrown away and another one built (even if the vast majority of the resultant DOM is identical to the previous page), and any plugins and embedded media are unloaded. There are various things you might be doing that this will upset, but one jumps out immediately: playing audio.
I hope the music plays forever
If you have an audio player on a site, I think it’s pretty obvious that you don’t want the playback interrupted every time you click on a link or otherwise move around the site. If you put the audio player in the page and don’t use CSR, then page loads will do just that, and we can all get behind the idea that this is a bad thing.
Now back in April 2010 I, and a bunch of /dev/fort folk, came together to do some work for a client we cannot name, but which might have had something to do with the music industry. Naturally, one of the things we built into the prototype we made was an audio player; and being somewhat contrary folks, and because we conveniently had a Ben Firshman to hand, we decided we wanted an audio player that didn’t require client-side routing.
(Actually, this was pretty much an essential for us to do what we wanted in the time available; with three designers and nearly a dozen developers creating and refining things as fast as we could, the idea of sitting down at the beginning and building out a CSR framework, then requiring everyone create work that could be dropped into it, really didn’t appeal. By avoiding the issue, we were able to have people treat every page they built as just another normal webpage; and Ben got to do something cruel and unusual in Javascript, which always makes him happy.)
And Ben managed it. The player itself lived in a pop-out window, with a Javascript API that could be called from other windows on the site so they could contain the media player controls you expect, showing what was playing and where it had got to, synchronised across any and all windows and tabs you had open. Even better, when you played a video, the audio player would be paused and unpaused appropriately. Finally, if due to some confusion or bug more than one player window was opened, they’d talk amongst themselves to elect a single ‘master’ player that would take command.
So it’s possible; but I wouldn’t recommend it. Mainly, the pop-out window is a bit ugly, and may conflict with pop-up blockers thus preventing you from hearing any audio at all, page loads or not. Secondly, the code gets quite complicated, and doesn’t really seem worth it if your site’s main aim is to play music, as say The Hype Machine or thesixtyone are doing.
The only thing I can think of in its favour is that it provides an obvious screen location for the active component of the player (be it Flash or whatever), which might help me out because for reasons unknown The Hype Machine never actually plays me any music at all on Safari. But putting up with ugliness and code complexity so that I can debug your site for you really doesn’t seem like a good trade-off.
This is the point that Hype Machine’s Anthony Volodkin made when he weighed in on the matter. He pairs it with some comments about UX that are disingenuous but not entirely wrong, as we’ll see later.
There is another point I’d like to make here, though: both Hype Machine and thesixtyone behave terribly if you open multiple tabs or browser windows. The lack of centralised player means that each tab will play independently of and ignoring the others, which means multiple songs playing over each other. If you rely on tabbed browsing, this is a bit upsetting (almost as much as things looking like links but not actually acting like them; note in passing that this is nothing to do with CSR, and that all of Twitter’s links on their site are real links, albeit using hashbangs). On the plus side, Ben has been thinking of writing a library to support the single-controller model he built, which would make this kind of thing much easier.
Other stateful enterprises
While preparing this article, I made some notes on two other reasons you might want to persist the state of the page (except for the interface responsiveness issue we’ll come to shortly). However both ended up with a question mark by them; although they seem perfectly sound to me in principal, I can’t think of anything significant that both has a need for one of them and has a need for deep-linking. Since I’m mainly interested in the intersection of good effects and bad effects of CSR with hashbangs here, these aren’t so interesting, but I’ll list them briefly for completeness.
computation: if you’re doing lots of work in the client (perhaps in Web Workers, or by doing sliced computation using setTimeout) then you don’t want the page to change underneath you. However in most cases the primary context isn’t going to change, so there’s no good reason for the URL to either, and you don’t need CSR so much as a way of stopping people from moving off the page, and there are already approaches to that. (Google Refine might do a fair amount of processing, but it doesn’t need a new URL except for each project; similarly Google Docs or similar only needs a new URL for each document. There’s probably some interesting corner cases here I haven’t considered, though.)
games: it occurs to me that you may want to have a web game with addressable (and hence linkable and sharable) sections that needs to keep client-side state. I suppose strictly this becomes either an issue of computation or interface responsiveness (or just not wanting to reload a chunk of state from the server, local storage or cookies), and in any case I can’t think of anyone actually doing this at the moment. (Of course, I’ve never played Farmville; those kinds of games might well benefit.)
Don’t Make Me Think
There’s a huge problem with web browsers as they currently work, which is that at some point between clicking on a link and the next page loading there’s a period where the window behaves as neither of the pages. If you’re lucky, the next page loads really quickly, and you don’t notice it, but there’s always a period where you can’t click anything, and sometimes can’t even see anything. Let’s illustrate this by loading Dustin’s tweet that I demonstrated with last time.
We see the new page start to load; at this point in most browsers the old page is still responsive.
But then we get a white page briefly.
Then we get the Twitter HTML coming in…
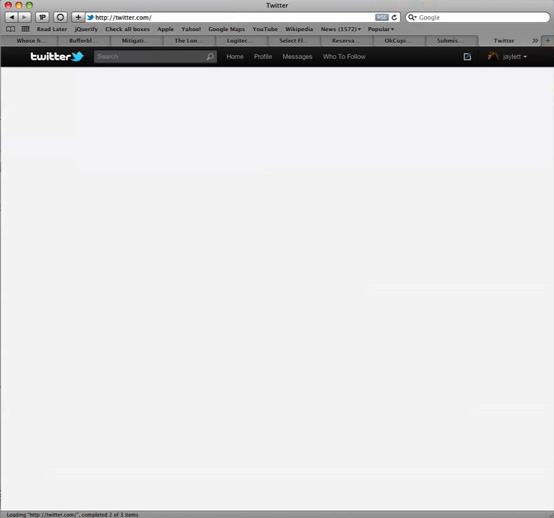
…and finally Twitter’s Javascript CSR loads the contents of my timeline.
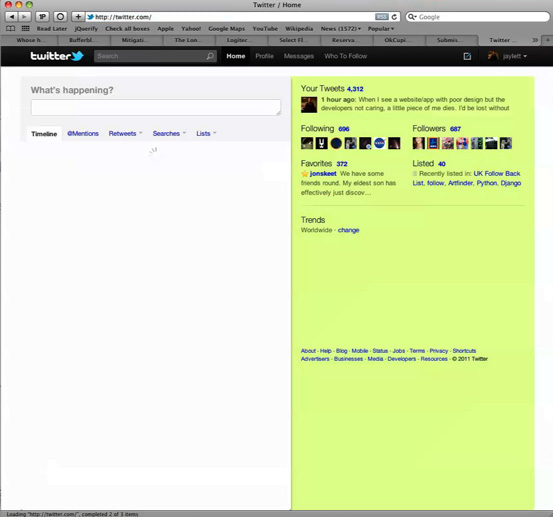
This actually happens in parallel to populating the right-hand side of the page, so the order that things appear isn’t fixed.
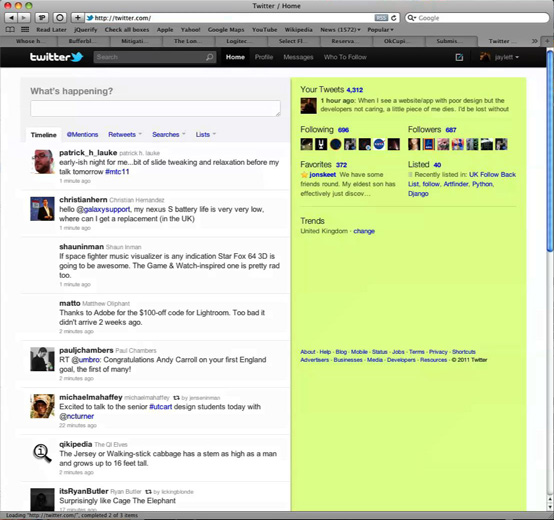
The entire thing took about a second for me as I recorded it as a video just now; it’s not a huge problem unless you have high latency or low bandwidth, and of course we’ve all learned to put up with it. However it is a genuine concern, as the longer something takes the more likely people are to get distracted during it.
I remember a much-touted point about an early version of the score writing software Sibelius was that every operation you could do, plus any redrawing of the screen, would be done in under a tenth of a second, which was supposed to be fast enough for people’s train of thought to be uninterrupted.
A brief diversion on distraction
I spent some time trying to find a reliable reference for the “tenth of a second” claim with no luck, although I’m guessing it related to the belief that it approximates the human reaction time (as noted critically by Wikipedia, for instance, although their article on mental chronometry does a better job). If you’re interested in human reaction time, there’s a 1982 article by Grice, Nullmeyer and Spiker which you can read for $12 or finding a student and buying them a beer.
Whatever the actual time required to interrupt a chain of thought, it’s clear that reducing the time of operations yields benefits. Google did some research in 2009 which can be taken to show that slower page loads result in less engagement with your site. (That’s not actually what it shows, but the paper itself is a single page without any detailed data to work with, and no discussion of confidence intervals; however it does show some impact on repeat engagement with Google Search based on slower page loads, and it marries sufficiently with common sense that we can probably go with the assumption that slow is bad until proven wrong.)
A brief diversion on latency
The Google paper talks about increasing the latency of search results, which informally means the time taken between doing something and seeing the result. Very roughly, an increase in latency is the same as increasing delay, as seen in this awesome cartoon.
Often when we’re talking about the web latency means network latency, which is the time between a computer (say a web server) sending some information (say a web page) and another computer (say your laptop) receiving it.
We usually measure network latency in milliseconds (ms), and they can range from very close to zero (for computers connected directly to yours) up to hundreds of milliseconds (say between one computer in London, UK and another in Perth, Australia). Between two computers about a mile apart in London, I see a round trip time (RTT) of about 22ms, giving the latency as about 11ms. From one of those computers to api.twitter.com gives an RTT of about 156ms, meaning 78ms latency.
And back to the topic at hand
Page loads on the web are generally slower than a tenth of a second; you’re only going to get that kind of speed out of the web for small pages from sites that are pretty close to you on the network (because of how brand new TCP connections work, you need a latency of under 25ms, and that’s not counting any time taken by the web server to process your request, or the web browser to render your page). Even 200ms is difficult to achieve for even small pages (50ms latency isn’t difficult when you’re within mainland US, but becomes difficult if you’ve got a lot of customers overseas and need to serve the traffic out of one data centre). Since Google were talking about 100-400ms showing a reduction in engagement, this has to be a serious consideration for anyone acting at scale (early-stage startups are more likely to be worried about getting more features up, and getting more users to play with them).
So the stage is set for us to introduce CSR to the problem. By asynchronously loading in new content rather than forcing an entire page load, we should be able to reduce the amount of data we have to transport, which might get us in under 400ms or even lower, but just as importantly, the interface remains completely functional throughout.
Don’t Make Me Wait
There’s a bit of an assumption going on here: that a responsive interface is enough to salve slow-loading content. In general this won’t be true (the fanciest interface probably won’t distract from taking ten minutes to load an image), but it would seem reasonable that there’s going to be a sweet spot where it’s better to spend time and effort on making the interface more responsive by using asynchronous loading than to spend the same time and effort trying to improve raw loading speeds.
After all, if a user decides they didn’t want something after they’ve asked for it but before it’s loaded, they just click somewhere else, and another async request will be fired off. Eventually something they’re interested in will load, unless you really can’t deliver content remotely fast at all.
A lot of people have grouped this under either “UX” or “performance”, which is unfortunate because they’re already both quite overloaded terms. I prefer to be precise about it, and say that the advantage here is around responsiveness, but we’re all getting at the same thing here. We want people to stay on our sites and keep on clicking around until, hopefully, we get to make some money, or kudos out of it, or at the very least get to stand next to celebrities and pretend we’re cool.
We’re not there yet
One of the dangers of imprecision is the conflation of different issues. You’ll note that CSR isn’t required for asynchronous loading of content at all; CSR is a way of making that content addressable by giving it a link that can be shared around. However not all content needs to be addressable.
I like to think of there being primary content, the “thing” you’re looking at, and secondary content which either relates to it in some way or is helpful in general. In terms of Twitter, primary content is the main timeline, searches, other people’s timelines, your followers and so on: the left-hand side of the web interface. Secondary content includes everything that goes in the right-hand panel: trending topics, favourites, lists you’ve been added to recently, and the conversation-ish view that pops up when you click on a tweet in the timeline. Secondary content can in some ways be considered to transclusion: including content within separate content, providing we talk quietly and don’t wake Ted Nelson.
When you don’t separate primary and secondary content, you wind up making mistakes; for instance, Ben Ward falls into this trap:
The reasons sites are using client-side routing is for performance: At the simplest, it’s about not reloaded an entire page when you only need to reload a small piece of content within it. Twitter in particular is loading lots, and lots of small pieces of content, changing views rapidly and continuously. Twitter users navigate between posts, pulling extra content related to each Tweet, user profiles, searches and so forth. Routing on the client allows all of these small requests to happen without wiping out the UI, all whilst simultaneously pulling in new content to the main Twitter timeline. In the vast majority of cases, this makes the UI more responsive.
This is misleading; the “small pieces of content” are generally pulled in without CSR, because the small requests aren’t the primary content of the page.
Here’s the thing. Primary content should be addressable; secondary content needn’t be. So secondary content isn’t going to benefit from CSR, and hashbangs don’t apply. (Twitter doesn’t make a hashbanged link for “your timeline with Dustin’s tweet highlighted”.) The only real similarity between them is that, with CSR, we can now load both asynchronously.
I argued last time you should consider not using CSR on “core objects” if you want a “safe” solution; these core objects are the same thing as primary content. But since CSR only benefits primary content, the conservative approach is never to use CSR at all. But we knew that; the interesting question is when you should use CSR.
The Tradeoff
The answer, as should be clear by now, relies on the relative importance of interface responsiveness compared the problems of limited addressability. It really needs considering on a case-by-case basis, and the trade-off relies on:
- how common an action is it?
- how fast is a complete page load compared to asynchronously pulling in just the new content, in the case of that action?
The former is down to a combination of UX design and user behaviour; with Twitter I know that I don’t often move far from the timeline, although I’d love to see hard data coming out from them about this.
For the latter, we have to start looking at performance. We’ll start by just looking at page sizes; but that’s for yet another separate article. I’ll try to complete it faster than this one.